|
Gaurav Singh
I am a second-year PhD student at Brown University, advised by Prof. Srinath Sridhar, at the Interactive 3D Vision & Learning Lab (IVL). My current work focuses on goal-conditioned deformable object manipulation with world action models, and more broadly on modeling deformable dynamics for robot manipulation, through both simulation and learned models. Email / Google Scholar / Twitter / Github |
|
News
|
ResearchMy research interests lie at the intersection of computer vision and robot learning. I am interested in neural models that learn to predict systems with complex, coupled dynamics, and in how those predictions can support decision making. More broadly, I work on visual representations and dynamics models for generalizable robot manipulation. |
| * Equal contribution / selected papers | |
|
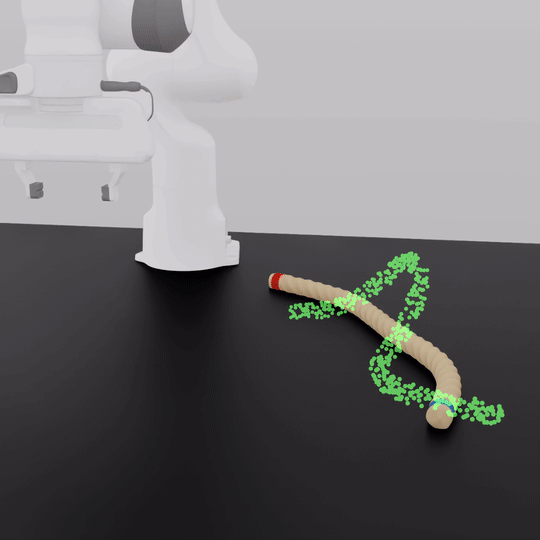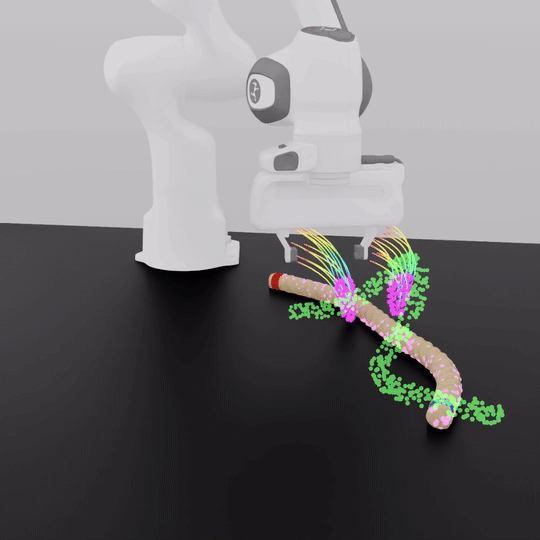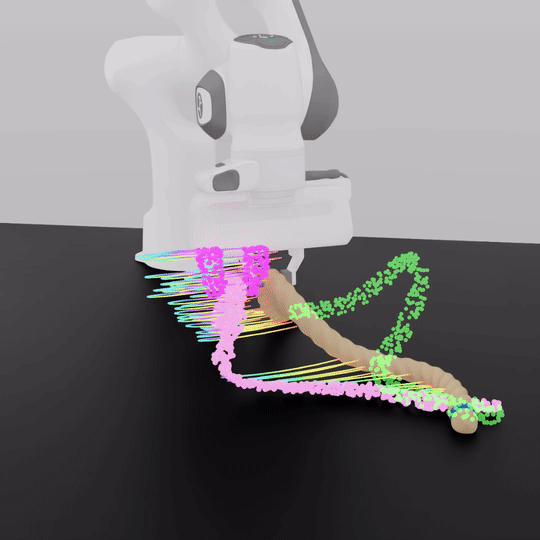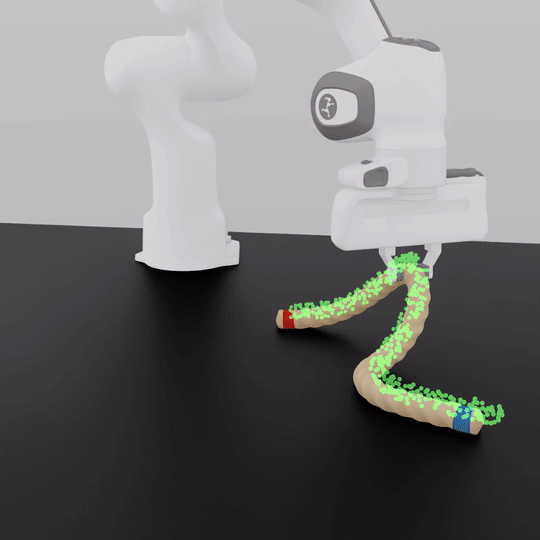
DefFlow: Goal-Conditioned Deformable Object Manipulation using 3D Point Flows
Gaurav Singh, Sergio Orozco, Ryan Duong, Mete Tuluhan Akbulut, George Konidaris, Srinath Sridhar Under Review project page / arXiv A goal-conditioned world action model for deformable object manipulation that jointly predicts robot motion and deformable dynamics as 3D point flows. |
|
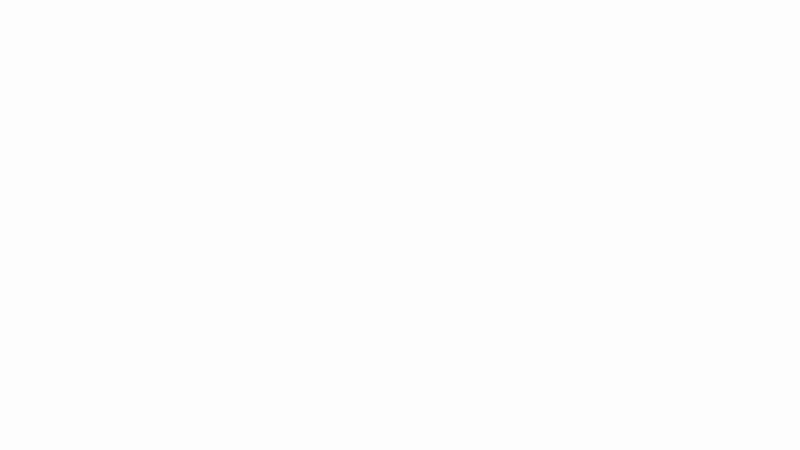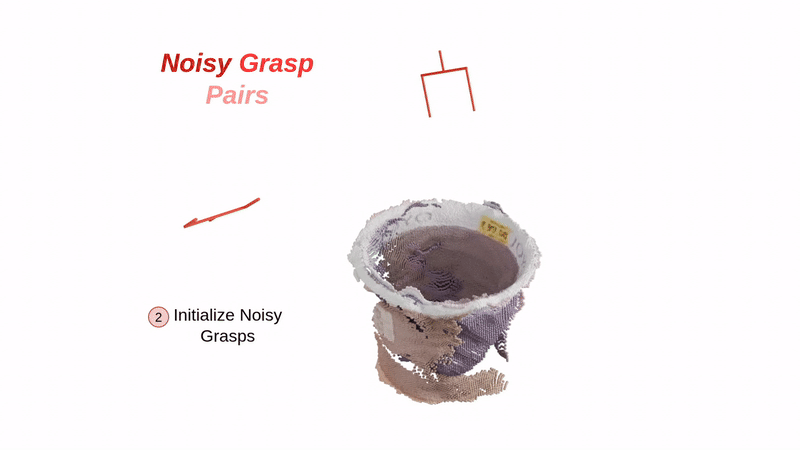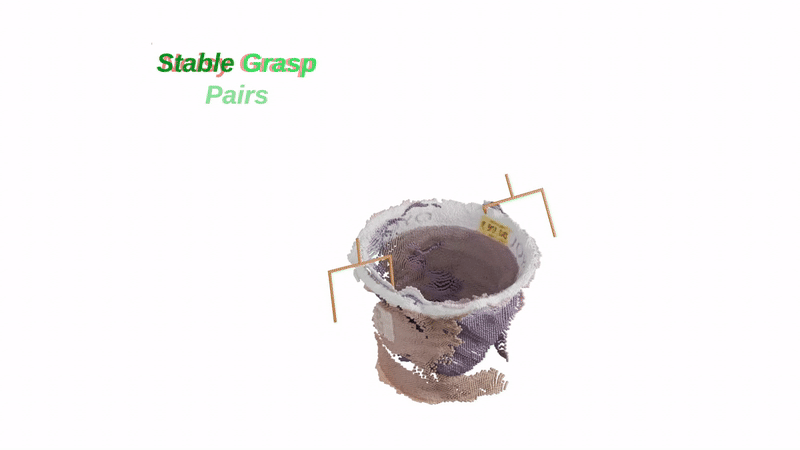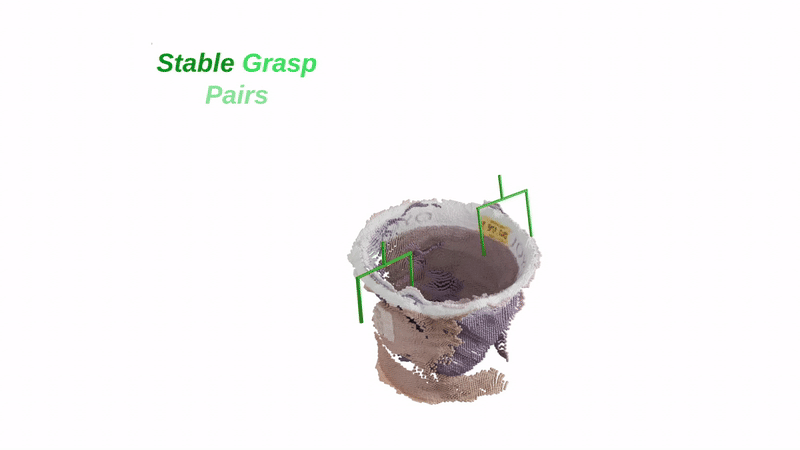
DAGDiff: Guiding Dual-Arm Grasp Diffusion to Stable and Collision-Free Grasps
Md Faizal Karim, Vignesh Vembar, Keshab Patra, Gaurav Singh, K Madhava Krishna ICRA, 2026 project page / paper / arXiv A diffusion-based dual-arm grasp generation model using stability and collision-aware guidance signals. |
|
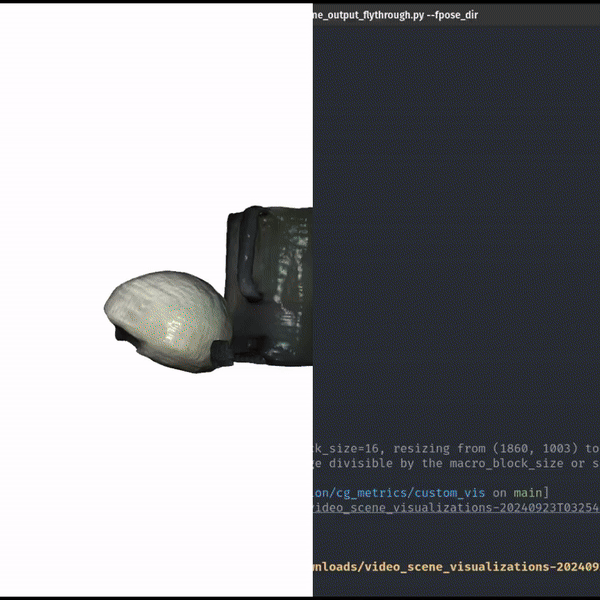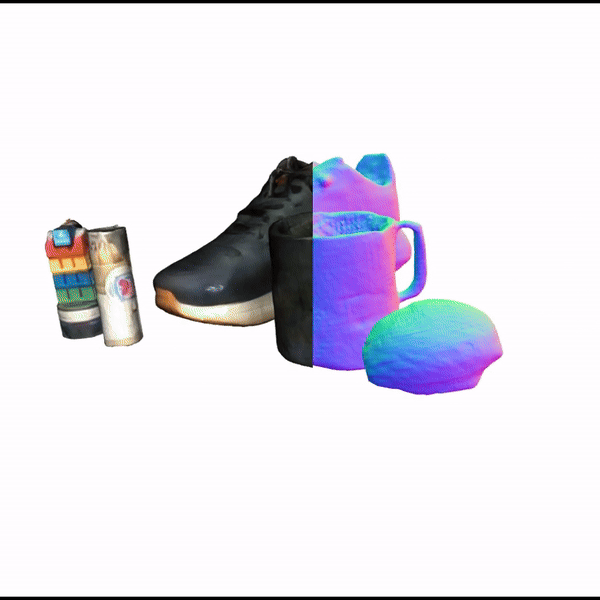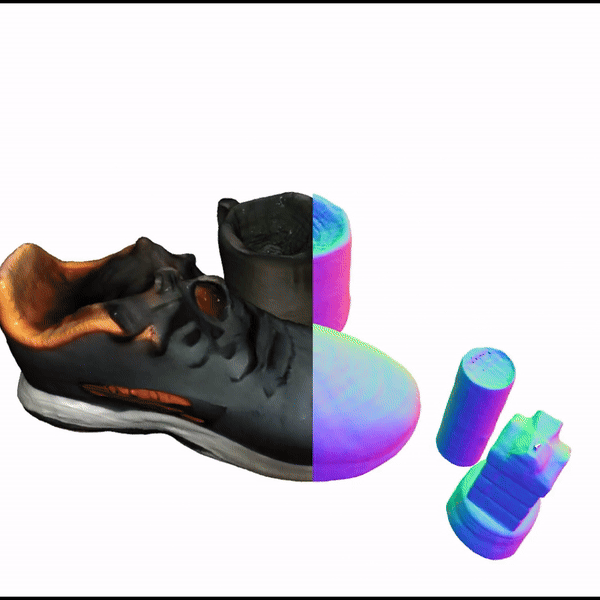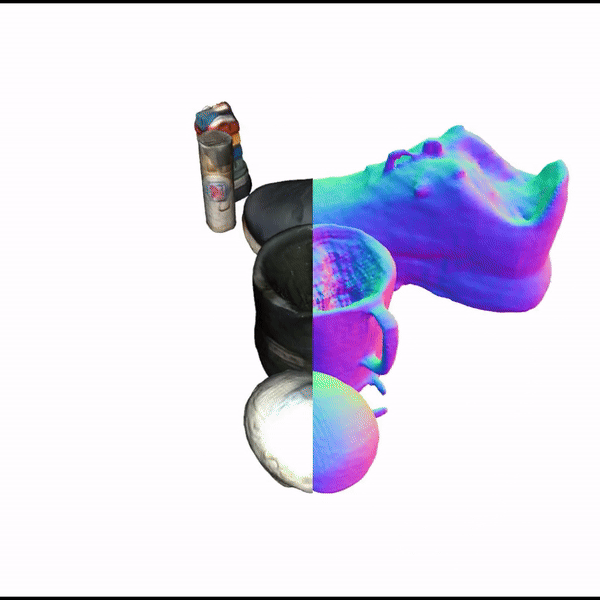
SceneComplete: Open-World 3D Scene Completion in Complex Real World Environments for Robot Manipulation
Aditya Agarwal, Gaurav Singh, Bipasha Sen, Tomás Lozano-Pérez, Leslie Pack Kaelbling RA-L, 2025 / ICRA, 2026 (Oral) project page / arXiv A novel pipeline for constructing complete, segmented 3D models from single views by composing pretrained perception modules. |
|
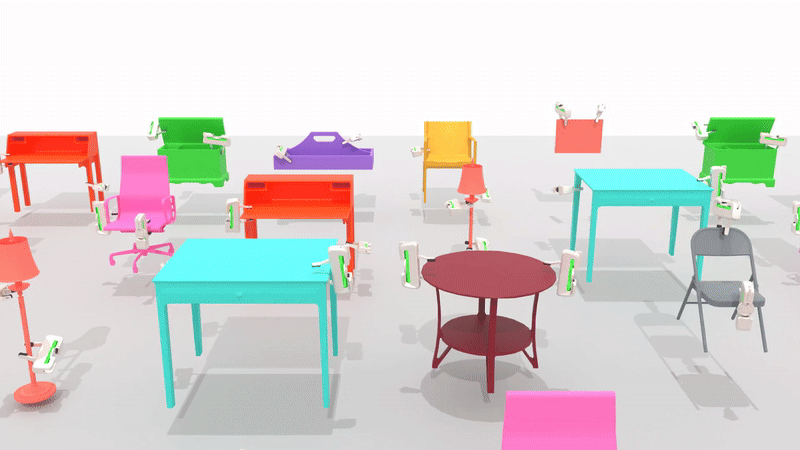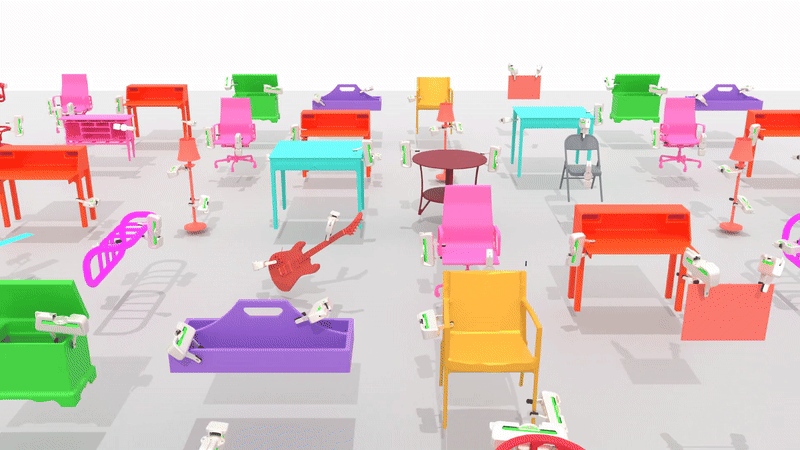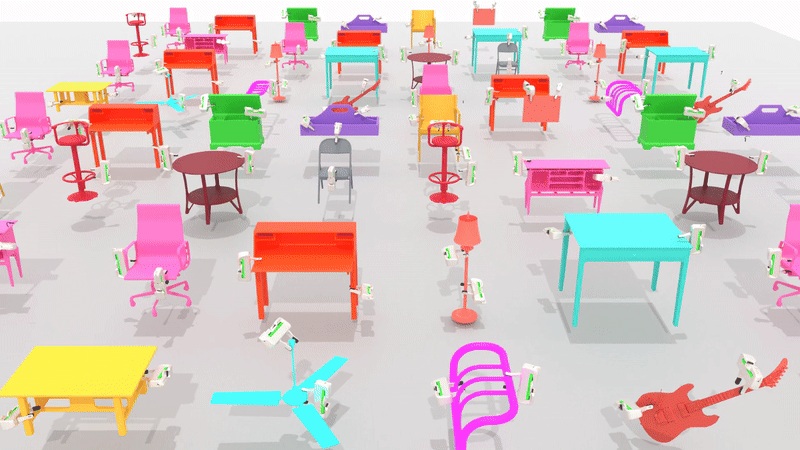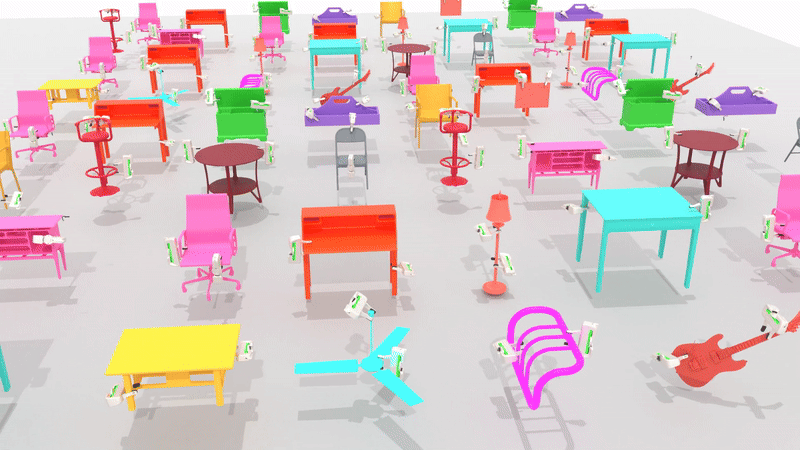
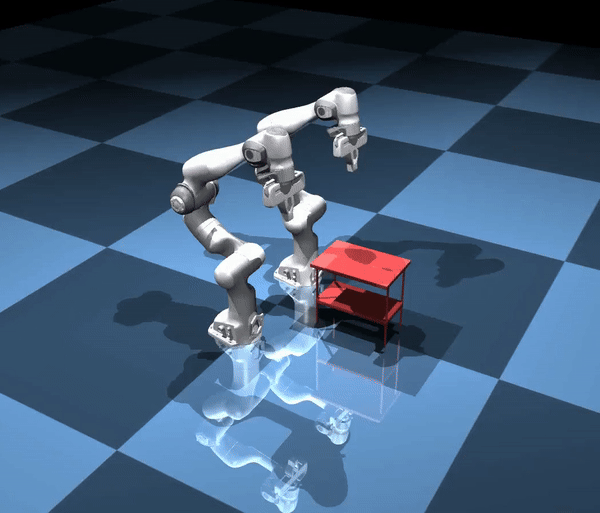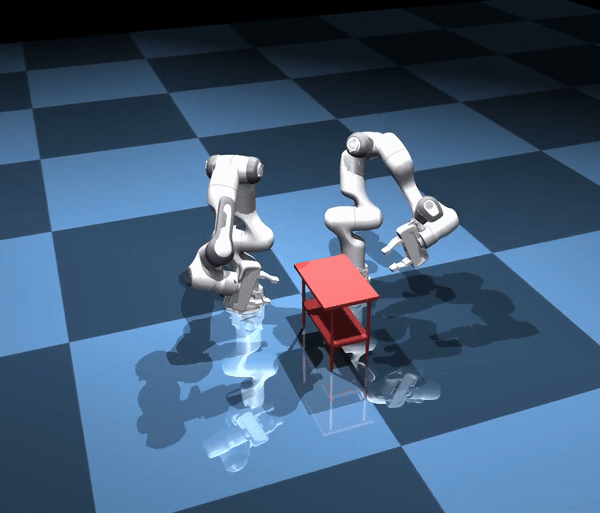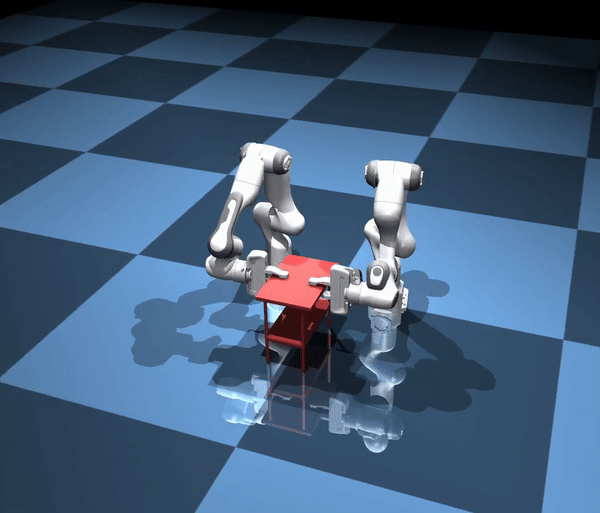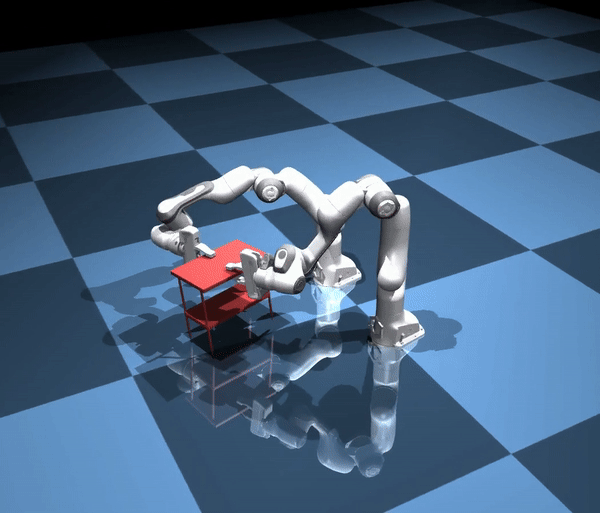
DG16M: A Large-Scale Dataset for Dual-Arm Grasping with Force-Optimized Grasps
Md Faizal Karim*, Mohammed Saad Hashmi*, Shreya Bollimuntha, Mahesh Reddy Tapeti, Gaurav Singh, Nagamanikandan Govindan, K Madhava Krishna IROS, 2025 project page / paper A large-scale dataset of 16M dual-arm grasps with force-closure constraints, enabling better grasp synthesis for dual-arm manipulation. |
|
DA-VIL: Adaptive Dual-Arm Manipulation with Reinforcement Learning and Variable Impedance Control
Md Faizal Karim*, Shreya Bollimuntha*, Mohammed Saad Hashmi, Autrio Das, Gaurav Singh, Srinath Sridhar, Arun Kumar Singh, Nagamanikandan Govindan, K Madhava Krishna ICRA, 2025 project page / arXiv A novel pipeline combining policy learning and gradient-based optimization for adaptive dual-arm manipulation with dynamic impedance control. |
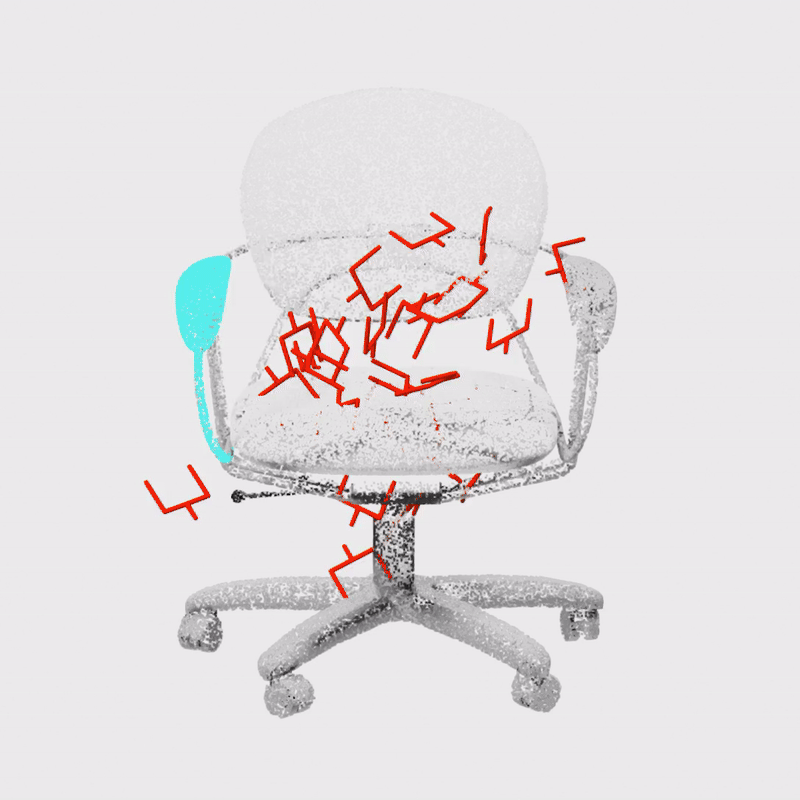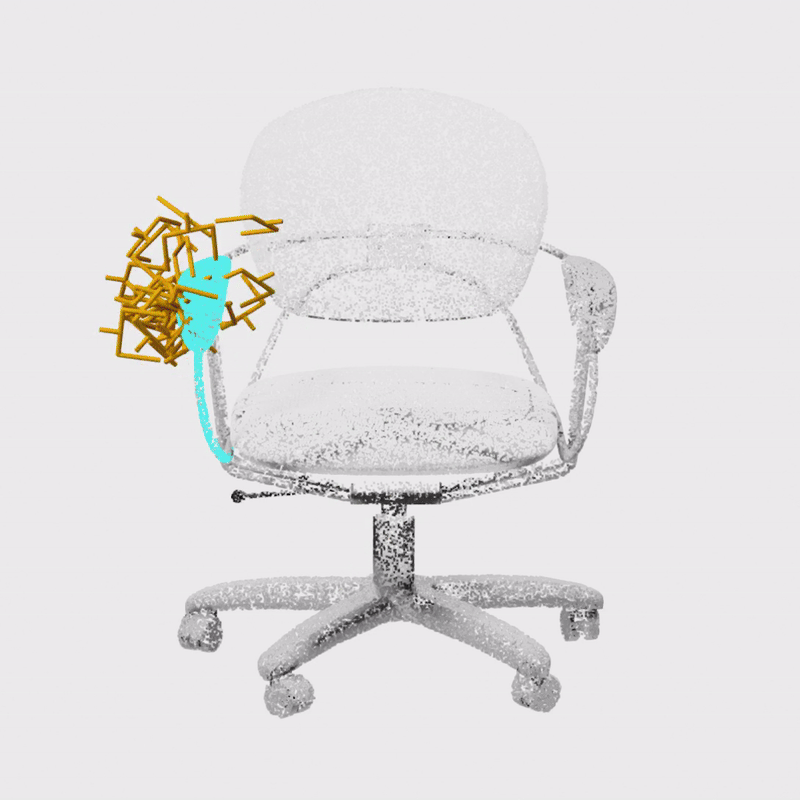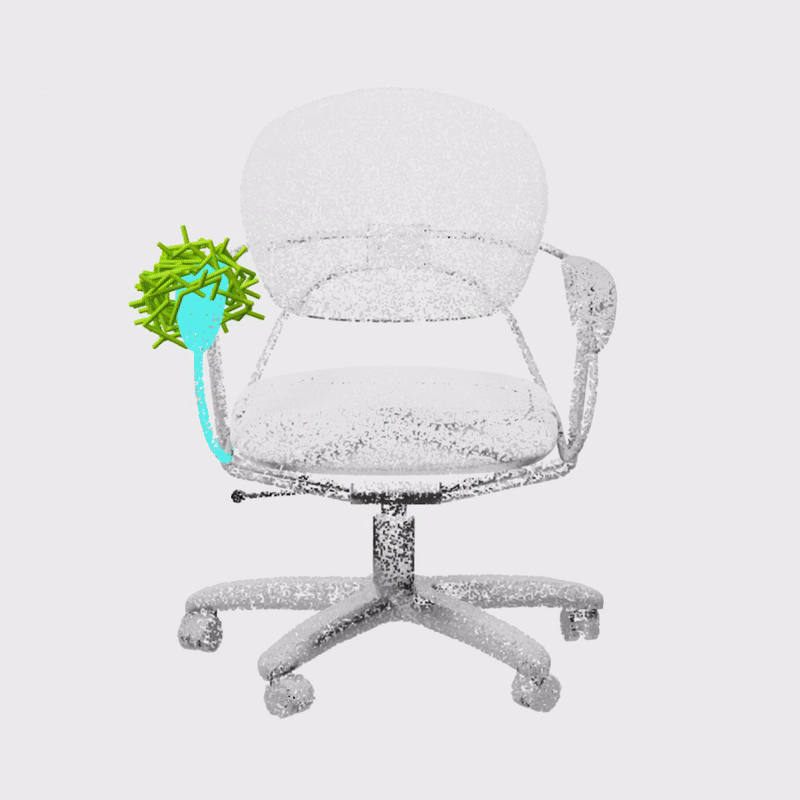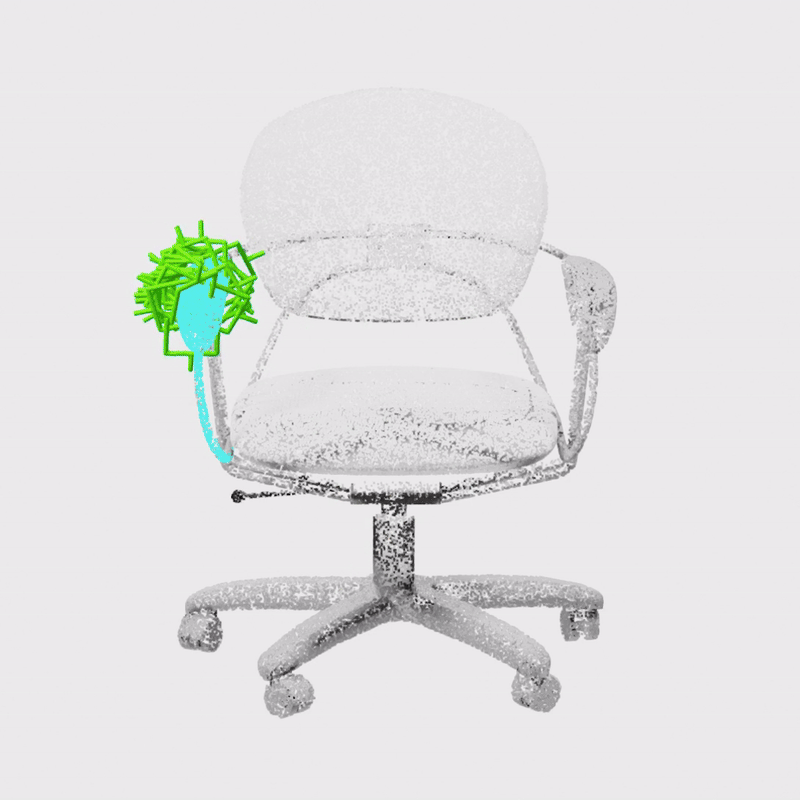
|
Constrained 6-DoF Grasp Generation on Complex Shapes for Improved Dual-Arm Manipulation
Gaurav Singh*, Sanket Kalwar*, Md Faizal Karim, Bipasha Sen, Nagamanikandan Govindan, Srinath Sridhar, K. Madhava Krishna IROS, 2024 project page / arXiv A diffusion-based grasp generative model that can generate dense grasps on target regions of complex objects without explicit constraint training. |
|
HyP-NeRF: Learning Improved NeRF Priors using a HyperNetwork
Bipasha Sen*, Gaurav Singh*, Aditya Agarwal*, Rohith Agaram, K. Madhava Krishna, Srinath Sridhar NeurIPS, 2023 project page / arXiv A hypernetwork-based approach for learning generalizable category-level NeRF priors with improved quality and multi-view consistency. |
|
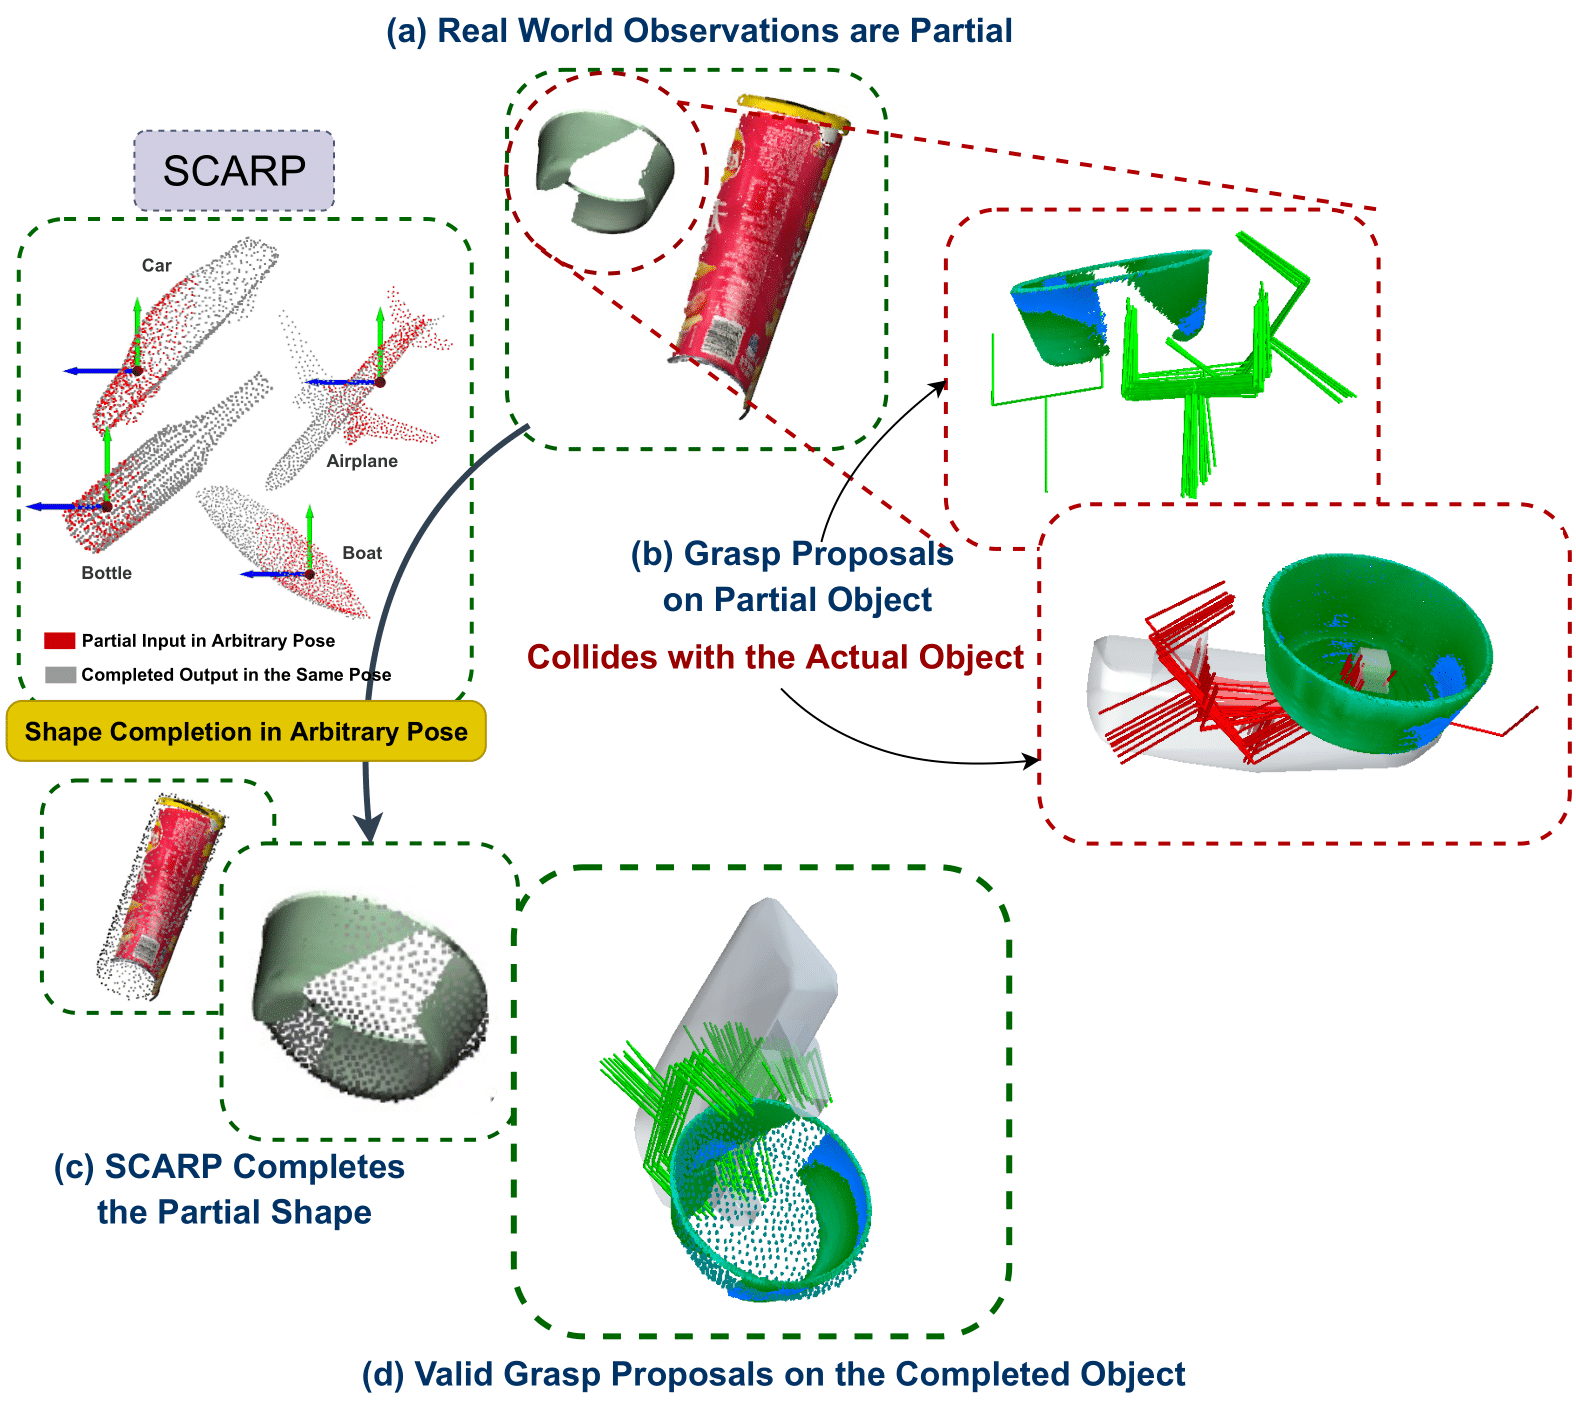
SCARP: 3D Shape Completion in ARbitrary Poses for Improved Grasping
Bipasha Sen*, Aditya Agarwal*, Gaurav Singh*, B. Brojeshwar, Srinath Sridhar, K. Madhava Krishna ICRA, 2023 project page / arXiv A model that performs shape completion in arbitrary poses by learning disentangled pose and shape features, improving grasp proposals by 71.2%. |
|
This website uses this template. |